
Consider a familiar request: “Every Monday, review last week’s sales and tell me what needs attention.”
To answer that request, an analyst needs to know which account to review, whether “sales” means order value or revenue after cancellations and refunds, and the exact dates covered by “last week.” Acting on a recommendation still needs the operator’s permission.
Software has to carry those assumptions explicitly. The account, metric definition, reporting window, available evidence, and permission to act all affect what a run can reasonably produce. Lose one of them along the way and the result may read well while answering the wrong question.
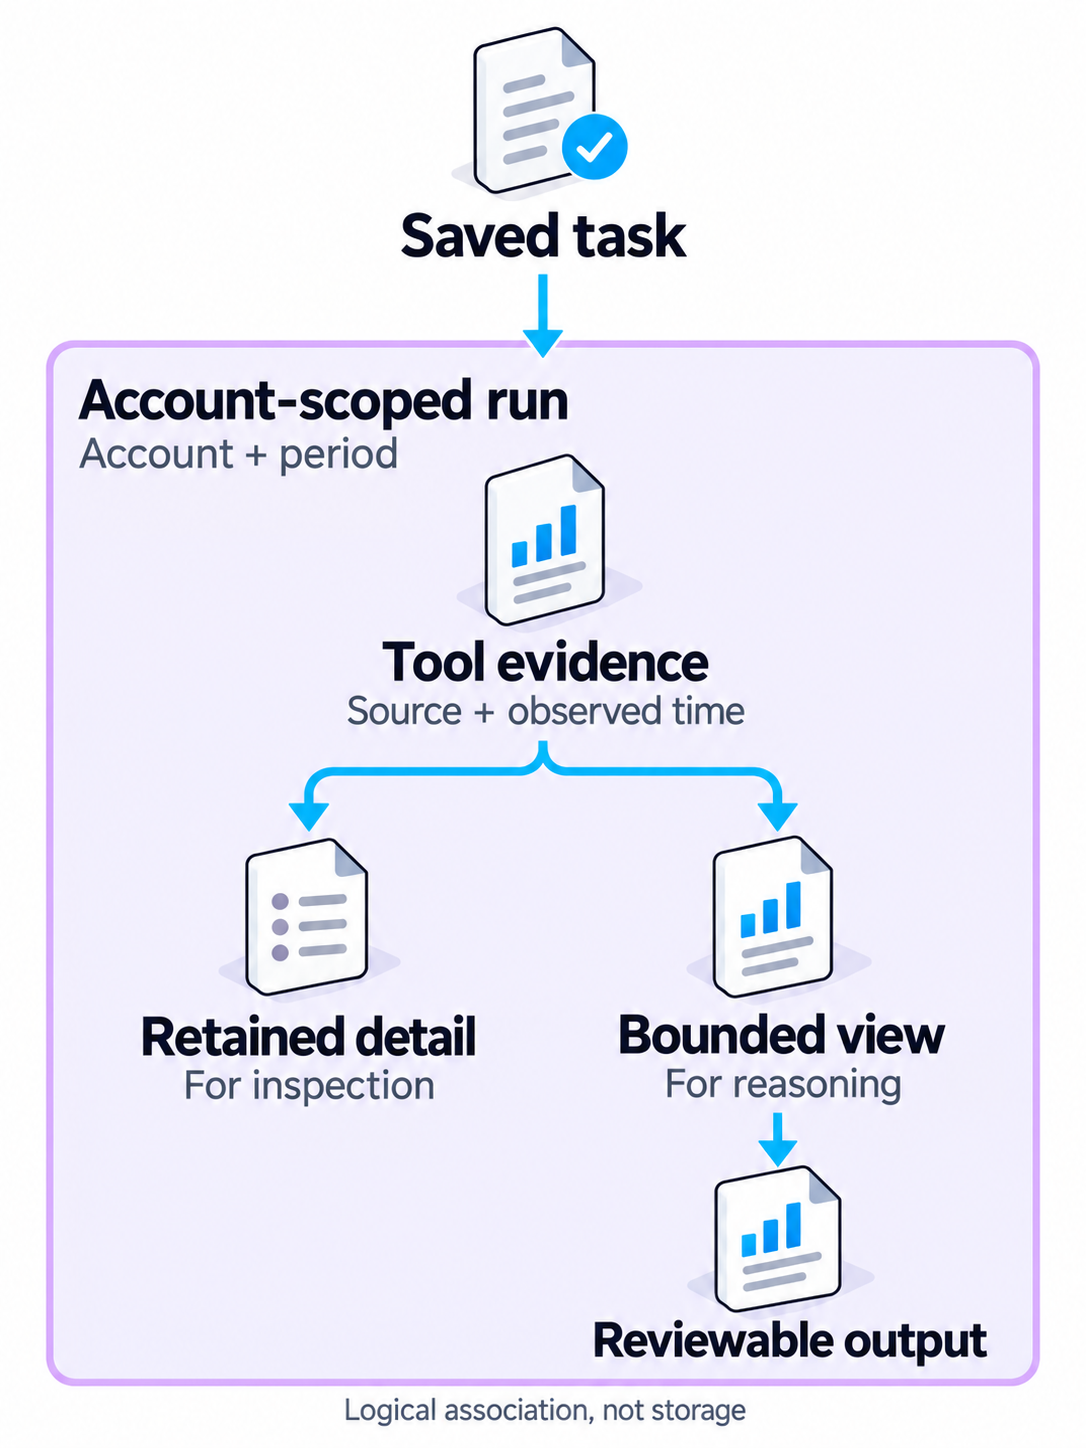
In Lumian Agent, recurring work connects a saved task to an account-scoped run. Tools gather evidence within that context. The run retains the work and its outcome so an operator can inspect what happened. This article follows that path, including the places where an agent should expose a limit instead of forcing a conclusion.
A schedule describes intent. A run records an attempt.
The weekly request contains two different things: work someone wants repeated, and a particular attempt to do it. A saved task holds the instruction, cadence, time, timezone, and chosen approval behavior. A run holds the account context and the record of what happened on that occasion.
Keeping them separate makes an ordinary operational question answerable: did the Monday job run, and what did it actually use?
The reporting window deserves the same care as the start time. A Monday morning report can accidentally compare a few hours of the current week with seven complete days from the previous one. Both queries may succeed. The comparison would still be misleading. For a weekly workflow, define comparable periods and show their boundaries in the result.
For an Amazon US account, the assumptions might look like this. The YAML illustrates the task and is not a configuration file to submit:
job: weekly-account-analysis
marketplace: Amazon.com US
account: selected-authorized-account
schedule:
  cadence: weekly
  timezone: America/New_York
  day: Monday
  time: "09:00"
reporting_window: previous-complete-week
compare_with: preceding-complete-week
output: evidence-backed-report
review_owner: account-operator
external_actions: require-review
This conceptual specification makes the account, period, and review boundary visible before any analysis begins. It also gives the operator something precise to revise. “Run it earlier” changes the schedule; “compare complete weeks” changes the meaning of the analysis.
Lumian identifies cadence slots to help reduce duplicate starts. A separate run record makes each attempt inspectable. Neither mechanism alone establishes exactly-once execution across an external system.
Context has to survive the handoff to tools
An operator can work across several accounts in the same day. “My inventory” is convenient language for a conversation, but it leaves a dangerous amount of room for interpretation in a tool call.
Lumian resolves authorized account context before the work proceeds. That scope travels into the run and its tools. A previous result in the conversation should not become an accidental account selector for the next task.
For the weekly report, the reader should be able to identify the account, marketplace, and period without reconstructing the conversation that started it. That context also makes the report easier to challenge. If the period is wrong, the operator can identify the error before spending time on the recommendations.
The run brings progress, tool outcomes, source provenance, final output, and action status into the same record. A final paragraph can summarize the work. The surrounding record lets someone check it.
Evidence needs to outlive the reasoning step
An agent can inspect relevant input readiness, call a tool, interpret its result, and decide what it still needs. Each step changes the evidence available for the next decision.
Take the weekly analysis. Suppose sales have declined and advertising spend has changed over the same period. Those are observations. Explaining one as the cause of the other needs additional evidence. The report should leave room for a reviewer to accept the observations while questioning the explanation.
That is why provenance matters at the finding level. A reader needs to know where a result came from and when it was observed. Lumian records tool outcomes and source provenance with the run. Detailed tabular results can be retained separately from the smaller view used during reasoning.
This separation addresses a practical constraint: the agent may need a compact view to reason about a large result, while a person reviewing the work may need the underlying rows. Compressing the reasoning context should not make the compact summary the only surviving evidence.
The run connects configuration, evidence and output. Detailed results can remain available for inspection while reasoning uses a smaller view.
For an operator, the useful sequence is concrete: inspect the change, examine the proposed explanation, then decide what to investigate or do. Each step should remain traceable to the evidence that supports it.
An empty result still needs an explanation
Freshness and completeness answer different questions. A recently updated source may cover only part of the requested period. A successful tool call may return no rows because there were no matching records, or because the required input is unavailable. Those outcomes should lead to different language in the report.
Lumian inspects relevant readiness and freshness signals and can expose pending, unavailable, or unresolved inputs. Some applicable jobs pause while data is pending. The behavior depends on the workflow and its inputs; there is no universal freshness gate to assume.
Return to the weekly report with an advertising input still pending. That limits an explanation involving advertising. An independently supported inventory finding may still be useful. The missing input belongs beside the affected conclusion, where the reader can see what it prevents the agent from establishing.
| What the run finds | What the reader needs to know |
|---|---|
| Evidence covers the requested period | The finding, its source, and the comparison window. |
| A required input is pending | Which part of the analysis remains unresolved. |
| Coverage ends before the requested period does | The actual coverage and the comparisons it can support. |
| Sources disagree | The disagreement and its effect on the recommendation. |
These are interpretation rules for a workflow, not a claim that every condition triggers identical automatic behavior. The operator should be able to distinguish “no issue found” from “unable to evaluate.”
A recommendation and an action need different records
A weekly report can recommend a change without changing the account. Most catalog agents produce analysis, reports, recommendations, plans, or assets. Their output needs to say what was prepared and what remains for someone to decide.
Supported write actions become reviewable action records. Interactive work waits for explicit approval. An autonomous schedule may execute a supported action when its saved approval setting permits it. Permission therefore depends on the supported action and the applicable saved setting. The presence of a schedule is not enough.
Review Requester makes this boundary concrete. It supports review requests for eligible orders. An interactive run asks for batch confirmation; a scheduled run follows the saved approval behavior. That specific capability does not imply that every agent can publish, file, or edit on an operator’s behalf.
Staging makes a supported action reviewable. Permission allows an attempt; the recorded outcome shows what is confirmed, failed or still unresolved.
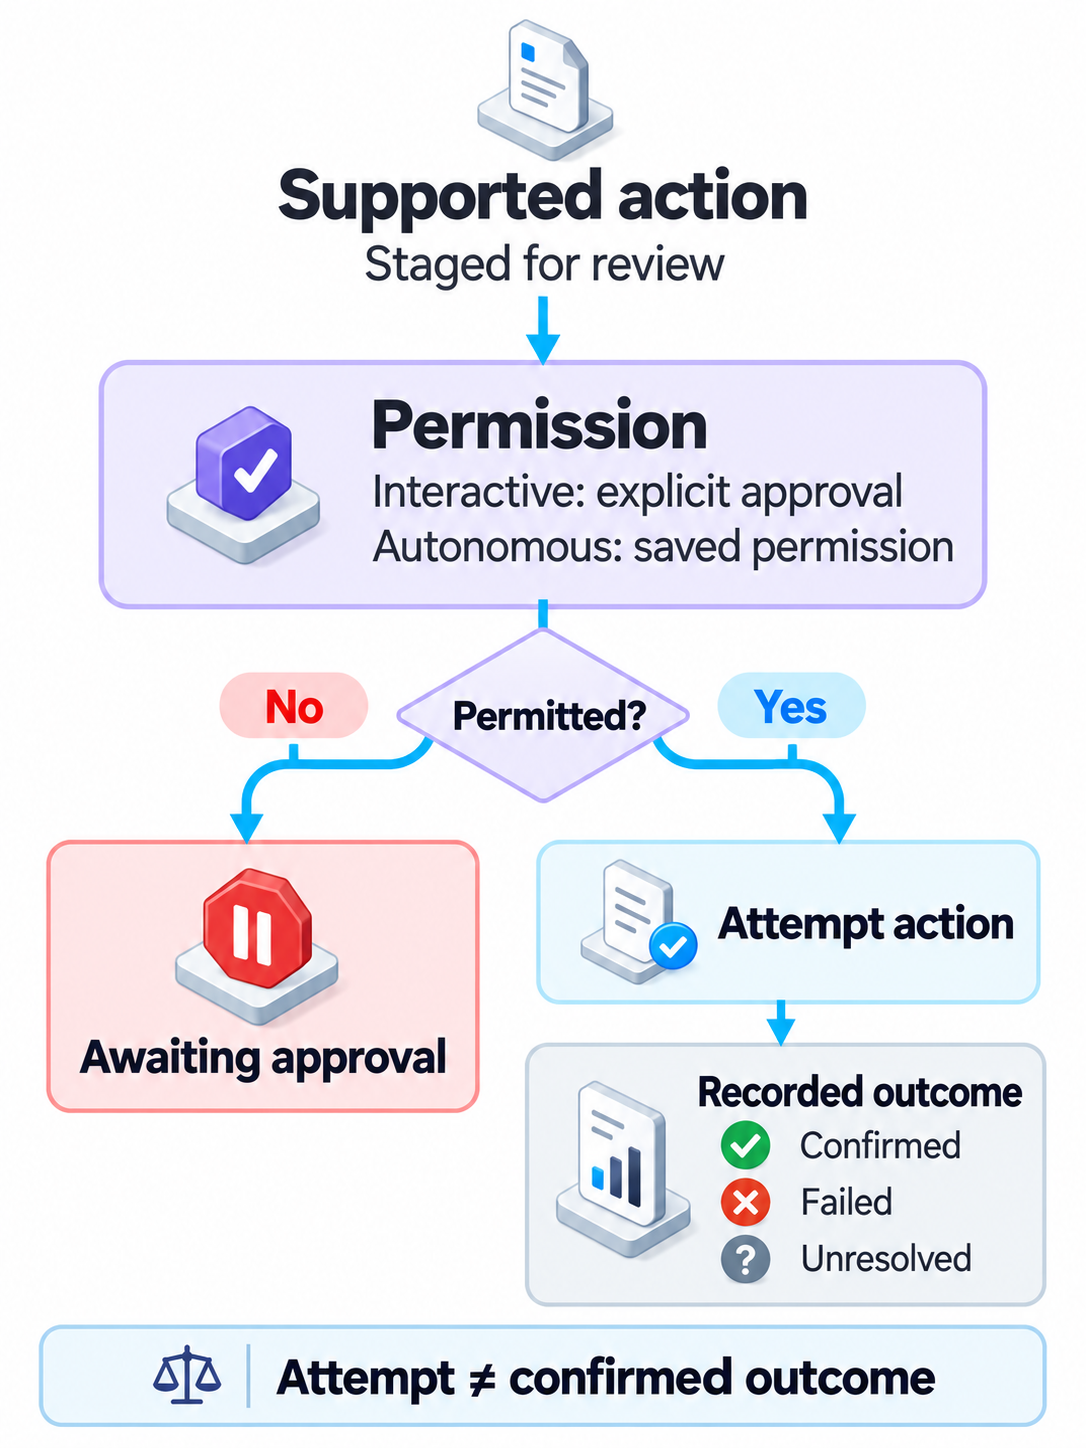
The conceptual control flow looks like this:
account = require_authorized_account(task.account)
inputs = inspect_relevant_inputs(account)
run = create_reviewable_run(task, account, task.approval_policy)

for step in plan_required_work(task, inputs):
    observation = call_allowed_tool(step, account)
    run.record(observation, source, observed_at)

    if observation.proposes_external_change:
        action = stage_reviewable_action(observation)
        if run.is_autonomous and saved_policy_allows(action):
            attempt_action_and_record_outcome(action)
        else:
            mark_approval_required(action)

persist_result_and_action_status(run)
The sketch leaves out implementation detail so the responsibilities stay visible. Gathering evidence, preparing an action, authorizing it, and recording its outcome each answer a different question about the work.
Completion depends on what the job promised
For our weekly report, completion means answering the requested question with traceable evidence and visible limits. For a prepared action, it means producing work someone can review. For an external action, an attempted submission still leaves the outcome to establish.
The difficult case is an uncertain response from an external system. A request may have been accepted even if its response never reaches the caller. Repeating it can create a second action. When designing such a workflow, the outcome needs reconciliation before a retry is safe to choose. This is a design consideration, not a claim that every Lumian workflow performs automatic reconciliation.
The same care applies when nothing changes. A report with an unresolved dependency should preserve that dependency. An action waiting for approval should remain visibly pending. A failed attempt should retain its failure. Smoothing those states into a reassuring completion message takes information away from the operator.
The weekly task becomes useful when someone can open its run and understand the account and period it used, inspect the evidence behind a finding, and see whether a proposed action remained a proposal or actually completed. That gives the next Monday’s run a clear standard to meet.
Start free with Lumian Agents to explore the available workflows for Amazon.com US.